Exploring User Engagement Through the Design of Modern Media Platforms
Published Jul 31, 2026Reads 626By John Pavlus
The design of digital media platforms shapes user engagement, blending intuitive navigation with interactive features to enhance audience connection.
Behind the Interface: The Design of Modern Media Platforms
The ceaseless flux of digital media creates spaces where engagement often shifts from traditional formats to interactive experiences. This transition isn’t merely aesthetic; it fundamentally influences how users interact with content. Take, for instance, the carefully orchestrated navigation elements of current media websites, visible in platforms like Quanta Magazine. These elements are finely tuned not just for function, but for the psychology of user engagement.
Consider the viewer's journey through the sleek layout that emphasizes accessibility and ease of use. Navigation menus should feel intuitive. The presence of a visible logo directing users to home, alongside a minimalistic layout, establishes a brand-first impression while simultaneously affirming trust. A straightforward design often reflects a commitment to a user-friendly experience, especially as the digital environment becomes more crowded.
Interactive Features and Their Impact
Now, let’s turn our attention to interactivity, which is vital in maintaining audience engagement. For example, how platforms incorporate podcast features signals a deeper understanding of today’s media consumption patterns. An interactive podcast button encourages users to explore audio content seamlessly, integrating it into their reading experience. This blurs the lines between written articles and audio discussions, enriching the way audiences connect with topics.
But the true measure of a platform's design might lie in its comment sections and share buttons, which are almost features of social engagement in their own right. Direct paths to comment, share, or bookmark an article fuel community discussions and social media sharing—both crucial for sustaining readership. Yet, one must question the efficacy of these features. Are they genuinely fostering insightful conversations, or are users merely skimming the surface?
In this rapidly evolving media landscape, the design of digital content isn’t just about aesthetics—it's about creating a cohesive experience that keeps audiences engaged. If you’re entrenched in this field, recognizing these patterns could be the key to enhancing user experience and retaining attention in a fragmented digital environment. As platforms push forward, assessing how well they connect and retain their audience becomes a pressing challenge, pointing toward a not-so-simple truth; effective design must be as dynamic and adaptable as its users.
The Complexity of AI Reasoning
What’s particularly baffling about the current state of AI reasoning is how rapidly perspectives shift. Just a few years back, terms like “large reasoning models” (LRMs) seemed to flicker in and out of favor, often evoking skepticism even among experts. Then came the jaw-dropping moment in May 2026, when an LRM from OpenAI tackled a notorious open mathematical problem—a feat so impressive that it stirred a flurry of excitement within the academic community. Suddenly, AI reasoning seemed legitimate, its capabilities hard to dispute. But should we take this at face value?
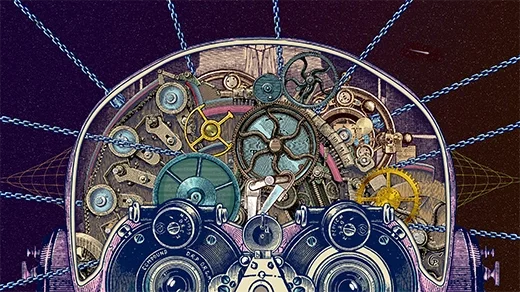
The process of reasoning, in essence, hinges on logically connecting intermediate steps to arrive at valid conclusions. Humans do this naturally; AI systems like LRMs attempt a similar feat using "chains of thought"—streams of synthetic text generated during problem-solving. However, there’s a growing consensus that what we perceive as reasoning might instead be a sophisticated mimicry rather than a genuine understanding. Researchers from Apple previously criticized this notion, dubbing it an “Illusion of Thinking,” and cautioning that these AI systems risk failing under minimal scrutiny. Surprisingly, the next thing we knew, these models were outperforming seasoned mathematicians in competitions like the International Mathematical Olympiad.
But here’s where it gets tricky. More recent studies indicate LRMs can navigate reasoning benchmarks using superficial shortcuts, putting into question whether they're genuinely reasoning or just exploiting system quirks. As excitement built over their recent victories, researchers returned to the reality of the situation: LRMs have documented limitations and failure states that beg for attention. This inconsistency raises a crucial concern: Can these models genuinely think, or do they simply produce answers that look correct?
Chains of Thought: A Double-Edged Sword
Let's zoom in on these proverbial chains of thought. They're supposed to represent the model's reasoning process, yet a mounting body of findings suggests they might not hold water. Research has shown that replacing these so-called traces with irrelevant information does not significantly compromise the model's performance on reasoning tasks. One compelling notion is that chains of thought could be more about appearance than substance—language that seems meaningful but lacks genuine relevance to the task at hand.
Take the work of researcher Subbarao Kambhampati. He bluntly pointed out that these “intermediate tokens" might just be linguistic mumblings rather than robust indicators of reasoning capability. He insists that while LRMs can sometimes produce impressive results, their underlying mechanics remain dubious, representing a mischaracterization of what it means to reason. In fact, academic research shows that text generated during reasoning tasks doesn’t impact the model's outcomes nearly as significantly as one might hope.
This leads to an unsettling implication: If those chains of thought aren't inherently meaningful or causally linked to outputs, can we genuinely call the process reasoning? Kambhampati’s frustration is palpable; he argues this rush to anthropomorphize AI outputs undermines rigorous scientific inquiry. Many in the field are all too eager to embrace narratives of capability, when, in fact, the picture is more nuanced.
On the flip side, advocates for LRMs, such as Sébastien Bubeck of OpenAI, downplay these critiques. He argues that older models suffered from limitations that newer iterations have resolved. While it's encouraging to see advancements in AI reasoning, skepticism remains justified until we establish a clearer understanding of how well these systems translate reasoning into consistent, meaningful outputs.
Rethinking AI Capabilities
In sum, while the capabilities of AI systems—especially LRMs—are impressive, they cannot simply be dismissed as mere illusions. Every expert I consulted acknowledged the successes, but they also pointed out the shortcomings that shouldn't be glossed over. There's a valid concern that promising claims about these models often overshadow problematic findings. Kambhampati’s call for clarity resonates: to truly grasp AI reasoning, we must look beyond the hype and understand both what these systems accomplish and where they falter.
Understanding AI reasoning may require acknowledging that our interpretations can diverge dramatically from reality. As we push the envelope in this technology, nuance isn't just important; it’s essential for developing a grounded approach to both the present and the future of AI.
The Complexity of Reasoning in AI
As we step back to assess the realm of large reasoning models (LRMs), it's essential to unpack the intricate layers behind their functionality. A critical point raised by researchers like Kambhampati and Bubeck emphasizes that despite the advanced capabilities portrayed by these models, the essence of their operations may not be as mystical as they appear on the surface. These systems often rely on training specific to their tasks, with Kambhampati arguing that what distinguishes LRMs isn't some secret sauce but rather a narrow focus within the architecture of large language models (LLMs).
Here's the crux: while LRMs can indeed produce outputs that mirror human reasoning, their process isn’t a meticulous journey through logical steps. Instead, it seems more like a probabilistic dance through a vast archive of learned information, often yielding results that feel logically derived without necessarily employing rigorous reasoning. Kambhampati’s assertion that LLMs primarily engage in “approximate retrieval” shakes the foundation of how we view AI reasoning, suggesting that what we perceive as thought may merely be a clever retrieval of contextually relevant snippets, rather than genuine understanding.
This calls attention to a significant dilemma. Bubeck's defense of OpenAI’s transparency regarding their models points to a stark contrast between what’s portrayed as the "thinking process" and the internal workings that generate this facade of reasoning. While claims of transparency abound—like the release of modified reasoning chains—there's an underlying concern: if these chains are merely curated outputs, are we witnessing the true mechanics of thought or just well-constructed illusions?
Kambhampati’s hypothesis fits into a broader narrative, one where LRMs might not genuinely learn reasoning methods but instead absorb patterns that allow them to produce convincingly coherent outputs. This brings us to an intriguing consideration: Can the success of LRMs truly be pinned down to their ability to mimic reasoning? Or are we merely witnessing sophisticated parroting, where accuracy is achieved without an accurate reflection of underlying processes?
Mitchell flags a thought-provoking perspective by comparing LRMs to tools like AlphaFold, which have produced transformative results even without transparent reasoning methodologies. If LRMs can indeed aid in fields like mathematics in the same way, does the underlying complexity really matter, or should we focus more on their outcomes? This binary thinking is seductive but hazardous. The allure of relying on LRM outputs without interrogating the reasoning—or lack thereof—could lead to blind spots in how we engage with these models in future research.
The criticism isn’t merely academic; it’s a pressing concern for anyone working with AI in critical sectors where verification matters. As Tal Linzen aptly noted, the reliability of an AI’s execution of algorithms—the bedrock of trust in AI systems—should not sway with subjective interpretations of reasoning. The possibility that an LRM could yield correct answers for arbitrary reasons raises alarms.
This ongoing discourse carries more than theoretical implications; it shapes how we build trust in AI outputs. As Kambhampati succinctly put it, viewing reasoning chains through an overly reverent lens may lead us down a "rabbit hole" that hinders technological advancement. This is where the balance lies: harnessing the capabilities of LRMs while rigorously questioning the integrity of their mechanisms.
As we engage with emerging models and methodologies, we must be vigilant about not being swept away by the allure of their outputs. The cautious optimism that accompanies advances in AI should be tempered by a critical examination of how those advances manifest. After all, in the intersection of technology and trust, understanding might prove more valuable than mere utility.
Discussion
Sign in to join the discussion.